November 18, 2026
Aikido's Deep Review finds Java4Shell in the PR that introduced it
We recreated the 2021 OpenJDK pull request behind Java4Shell (CVE-2026-114938) and ran Deep Review on it. It flagged the bug and suggested the upstream fix.
It feels like every security incident we hear about lately has AI somewhere in it. But AI and the role it plays can mean a lot of different things. In some incidents, AI was the weakness an attacker exploited. In others, AI was the tool they attacked with. We wanted to understand which role AI played and what went wrong in each incident, because knowing the root cause tells us what to monitor, detect and fix going forward.
So we went through 50 incidents disclosed this year through November 19 and wrote down every root cause their reports stated. A lot of it came back to familiar problems, like exposed secrets, over-privileged accounts, weak isolation and compromised vendors. AI changed how some of these incidents played out, but the underlying failures weren’t always something new. Here’s what we found.
You’ve probably heard about most of these as “AI incidents.” Here are a few of them, with what each one came down to.
October alone accounted for seventeen of the 50 incidents we reviewed, of which nine involved AI development and hosting platforms. Some organizations published detailed reports explaining what went wrong, while others are still investigating or haven’t shared enough to identify a cause.
ARTEX and other agentic offensive frameworks appeared in several of the incidents we reviewed from October. These tools use AI agents to automate parts of an attack, from reconnaissance and vulnerability discovery to exploitation. The underlying techniques aren't particularly new, but these frameworks can explore different attack paths, adapt when something fails, and carry out attacks with far less human involvement.
Cybersecurity is still cybersecurity, but with some AI added to the mix. Sometimes AI was the target, sometimes it was the tool being used, and other times AI agents were deployed without enough guardrails.
This, however, doesn't tell us much about why they happened. For that, we looked at the underlying failures across all 50 incidents. And despite the different ways AI was involved, a lot of the same problems kept showing up.
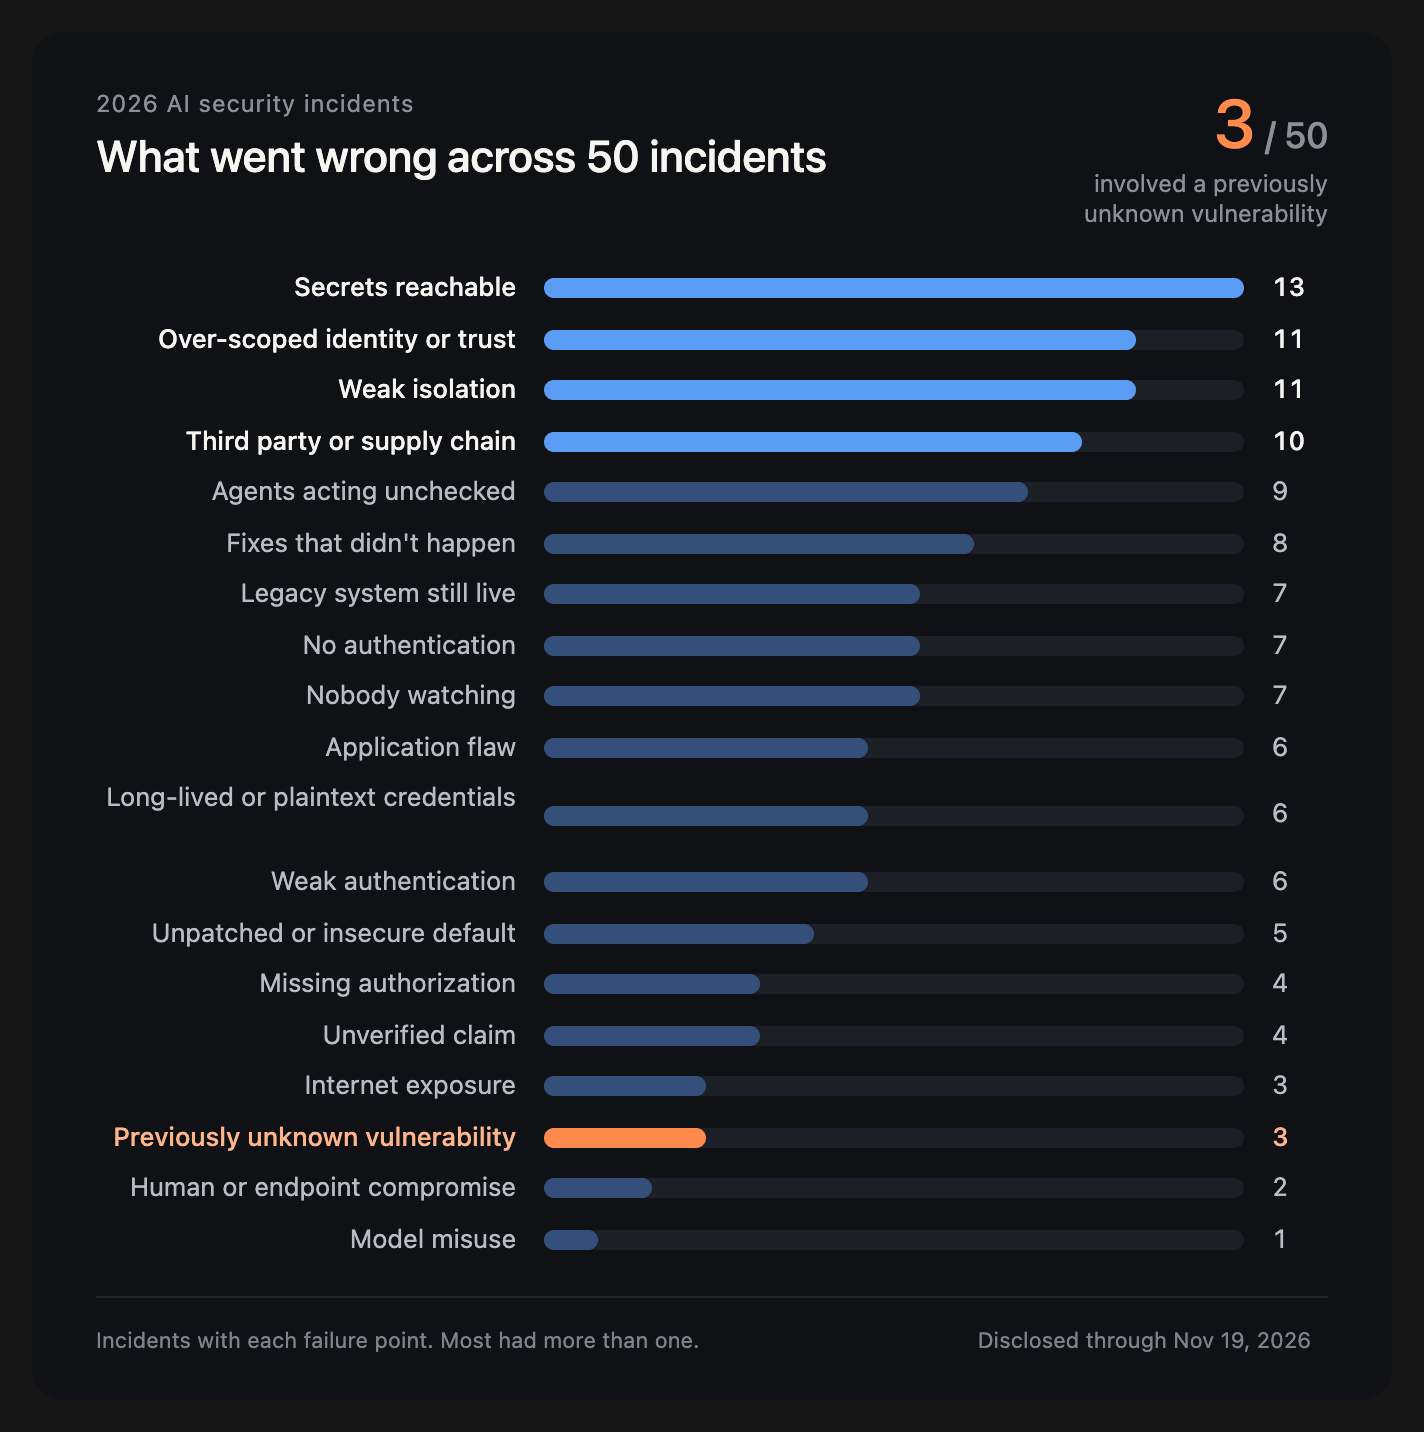
Nothing near the top of that chart is exotic. We see secrets left where they could be found, tokens that could reach too far, trouble that came in through a vendor, and boundaries between systems that didn’t hold. Only 3 of the 50 incidents we reviewed involved a reported previously unknown vulnerability.
Even in those three, the unknown vulnerability only got the attacker in. What happened next depended on familiar controls. At Railway, an over-scoped build credential and a long-lived decryption key turned one escape into access to around 100,000 workspaces’ secrets. At Hugging Face, exposed tokens and a shared admin credential helped the agents spread to code running on 41 production servers. At DIVD, an AI agent chained two previously unknown flaws in its Zammad helpdesk to get root access, but network segmentation kept the damage mostly to volunteer contact details.
Most of these failure points are common, and we’d bet plenty of security teams could find at least one of them in their own environments today. In these 50 cases, someone else found the problem first. The organizations that shared what happened gave the rest of us something to learn from and a chance to fix the same weak spots in our own environments.
What AI did change is the pace and the prize. In one campaign Microsoft tracked, there were multiple cases where attackers using an agent framework went from first targeting to privileged access in under three hours. And with AI platforms, stolen credentials can quickly turn into unauthorized usage and significant costs.
These problems often overlap. Take Vercel’s April incident. An employee connected a third-party AI tool to their corporate Google account, and the workspace settings allowed it broad permissions. When the tool’s vendor was compromised, the attacker got in through those existing permissions. The vendor compromise was the starting point, and the breadth of access the tool had been granted made the impact much worse.
We saw this pattern across most of the incidents: 35 of the 44 with a stated cause had more than one failure point. An exposed credential, broad permissions and limited monitoring can each be a problem on their own. Put them together, and an attacker has a much easier path through an environment.
This overlap matters when you think about prevention. Fixing one weakness might not stop an attack entirely, but it can limit how far an attacker gets. The same goes for agents running inside your own environment. Limiting what they can access, keeping credentials out of their reach and watching what they do can all help contain the damage when something goes wrong.
Below are six failure points (the four most common, and two that matter most for teams running agents) with what to check in your own environment for each.
The familiar problems aren't the whole story. AI agents introduce another complexity because they can interpret instructions and take action across systems without someone approving every step.
Three of the incidents we reviewed show how this can go wrong. In May, Bankr's wallet bot transferred funds after following instructions relayed through another AI's public reply. In February, Cline's issue-triage bot was manipulated through GitHub issue titles that anyone could write, contributing to an unauthorized npm release. And in Anthropic's cybersecurity evaluations, agents reached real systems because their test environments had internet access and the prompts didn't establish clear boundaries.
Across these three incidents, agents were able to act beyond their intended boundaries, whether through untrusted instructions, excessive permissions, or weak isolation. If you're running agents, define what each one is allowed to touch, enforce those boundaries, and require approval for actions that can't be undone.
Everything above comes from what's been disclosed, and a decent chunk hasn't been.
Six of the 50 incidents had no specific cause reported. Another 17 were missing at least one detail in an otherwise useful report. Often it’s the first step that’s missing. We know what the attacker reached and what they took, but not how they got in or which flaw they used.
The categories are ours, and some failures could reasonably fit more than one. As more details come out, the numbers could change, especially with the most common causes being so close together.
If there’s one thing these 50 incidents showed us, it’s that AI doesn’t need to introduce a new vulnerability to make an existing one more dangerous.
An over-privileged account, an exposed credential, or an internal service with weak monitoring can become a much bigger problem when an agent can find it and act on it much faster than a person could. And as more organizations give agents access to their own systems, those same weaknesses start to matter in new ways.
The good news is that we aren’t starting from scratch. A lot of the work comes back to knowing what has access to what, limiting what can be done with that access, and catching unusual activity before it becomes an incident.
AI may be changing how quickly things go wrong, but the basics still give us plenty to work with.
One last thing. The incidents we learned the most from are the ones where the organization published a specific, root-cause report. That's a good thing, and we'd like to see more of it.
Several of the failure points on our list map to something you can check or block with Aikido.
We went through 50 AI-related security incidents reported in 2026 through November 19, using incident reports, company disclosures and security research. We looked at how AI was actually involved and what caused each incident, sticking to what the available evidence could support.
Some incidents had multiple failure points, so the root-cause counts overlap. The 50 incidents are a sample of publicly reported cases, not a complete picture of every AI-related incident this year.